Large Language Models Explained
What is really inside a chatbot. Large language models learn to predict the next word from huge amounts of text. How they are trained, why they sound smart, and where they slip.
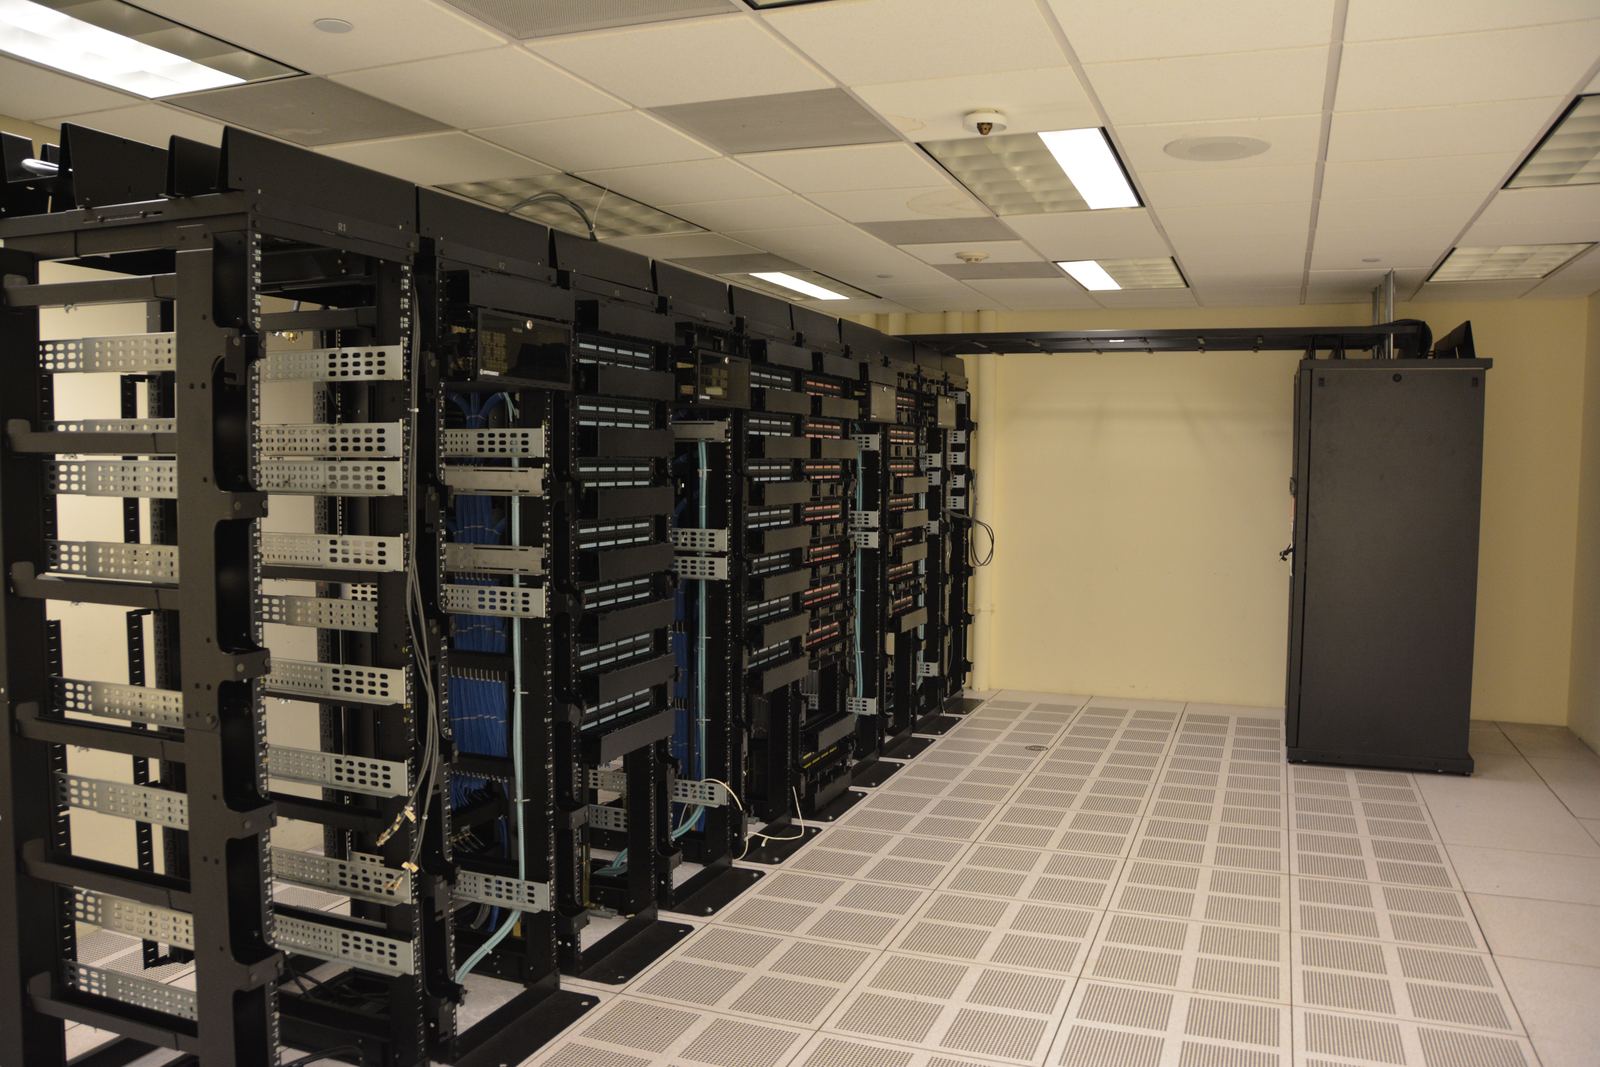
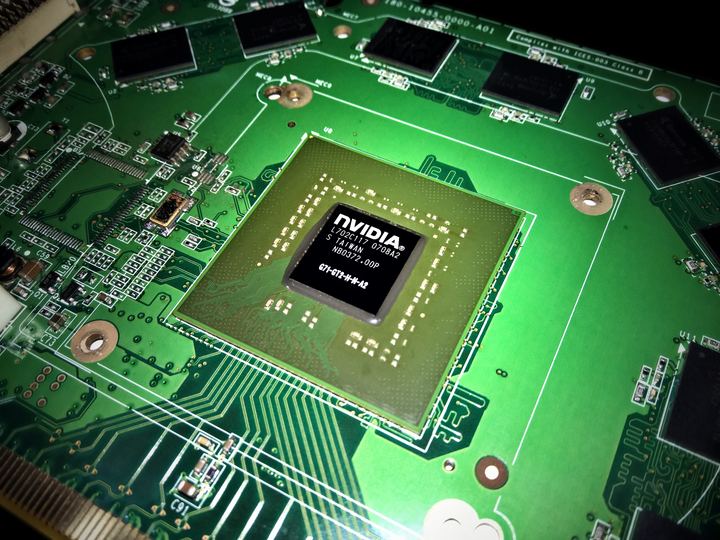
Language models are trained in data centers: Carl Lender from Sunrise, USA, CC BY 2.0
A very well-read autocomplete
At heart, a large language model does one thing: given some text, it predicts what comes next. Text is split into tokens, which are whole words or pieces of words. The model looks at the tokens so far and produces a probability for every possible next token. One is picked, added to the text, and the process repeats, which is how a full answer appears a little at a time.
That sounds simple, but predicting text well requires picking up grammar, facts, styles of reasoning and a great deal about how people communicate. To guess the next word in a chemistry textbook or a legal contract, the model has to absorb a lot about chemistry or law.
Video: Large Language Models explained briefly (3Blue1Brown), embedded from YouTube.
How they are trained
Training happens in stages. In pretraining, a Transformer network with billions of adjustable numbers, called parameters, reads an enormous amount of text gathered from books, websites, code and other sources. Each time it guesses a next token wrong, its parameters are adjusted slightly. This step takes huge clusters of specialized chips running for weeks or months.
The result is knowledgeable but not yet a good assistant. A second stage, fine-tuning, teaches it to follow instructions and hold a helpful conversation, often using examples written by people and feedback in which humans or other models rate its answers. Developers also train in safety behaviors, such as declining clearly harmful requests.
Why they make mistakes
An LLM produces text that is likely, not text that is guaranteed true. When it lacks reliable information it can still write a confident, fluent answer, a failure known as hallucination. It also has a context window, a limit on how much text it can consider at once, and its built-in knowledge stops at a training cutoff unless it is connected to search or other tools.
Models can reflect biases in their training data and can be thrown off by oddly worded questions. That is why good practice is to treat answers as a strong first draft and to check anything that matters.
What they are good at
LLMs shine at drafting and editing, summarizing long documents, explaining ideas at different levels, translating, brainstorming and writing or reviewing code. Many can now also take in images and audio, and newer reasoning models spend extra computation working through a problem step by step before answering. Used with care, they are among the most flexible tools ever built for working with words.
- arXiv: Attention Is All You Need
- OpenAI: Introducing ChatGPT
- Google AI for Developers: Prompt design strategies
Facts on this page were checked against these sources.
- Language models are trained in data centers: Carl Lender from Sunrise, USA, CC BY 2.0
Text written by Strawberry Lemonadai.